A second arm, not controlled by the policy, holds a container with a threaded cap. The operator positioned the gripper over the cap and triggered the unscrewing routine (close, rotate, open, rotate back, close, rotate, lift). The baseline policy has to reproduce the multi-turn motion from images alone; in its failures it turns the cap once or twice and then lifts while the cap is still threaded. Ours is Hybrid Imitation Learning on Diffusion Policy with the learned primitive channel; DP is the same Diffusion Policy trained on the same TAP-collected demonstrations without the channel. Seven initial configurations, sampled with the same seed for both policies, each executed three times (21 rollouts per policy): Ours 14 (67%) vs DP 8 (38%) successes. Below, all 21 rollouts per policy: one video per initial configuration, each showing the three repetitions of that configuration back to back.
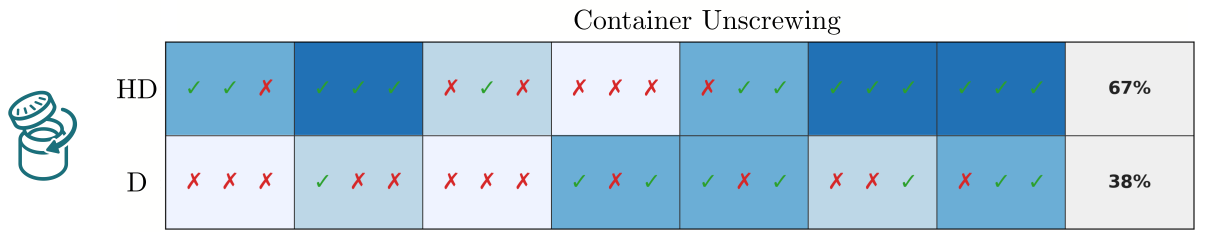
Outcome of all 21 rollouts per policy (pos 1–7, three repetitions each). HD: Ours; D: baseline Diffusion Policy.